Hire Compiler & Agentic AI Engineers in 24 Hours
Scale your AI engineering capabilities overnight. RapidBrains connects enterprise teams and fast-growing tech companies with pre-vetted, remote Compiler & Agentic AI Engineers ready to deploy under 24hrs.
The smartest way to hire remote developers on contract
Hire the best talent worldwide
Gain access to a talent pool of 500,000 and hire top developers from anywhere in the world.
Reduce employee cost by 70%
Hire remote developers with strong technical and communication skills at an affordable rate of $12/hour
Expand without a legal entity
We ensure compliance with local labor laws and provide legal insulation when you hire dedicated developers
Zero hiring cost
Hire offshore developers, interview talents free of cost, and pay only when they start working
Daily work report
Stay updated on project progress with daily work reports from offshore experts.
Time monitoring tool
Track work hours accurately and ensure productivity with a powerful time monitoring tool.
Employee management portal
Manage your global team effortlessly with a user-friendly employee management portal.
Payroll management
Streamlined payroll management, so you can focus on growth without administrative worries.
Global talent platform to hire the top
Developers.,Architects.,Technical Leads.,Consultants.
Starts from
$19/hour
Mid level developer
Starts from
$25/hour
Senior developer
Starts from
$29/hour
Lead developer
Experience the future of remote hiring!
Partner with us to access the best brains in the world
Our mission is to help companies boost profitability by optimizing workforce costs, while our vision is to create opportunities for all by seamlessly connecting the right talent with the right organizations.
500k+
Total talents
85+
Countries served
1.5k+
Happy customers
16+
Years in industry
Connect with Top Talent Around the World!
Trusted by 1.5K+ customers, we connect you with expert Shopify React contract developers.
The process flow
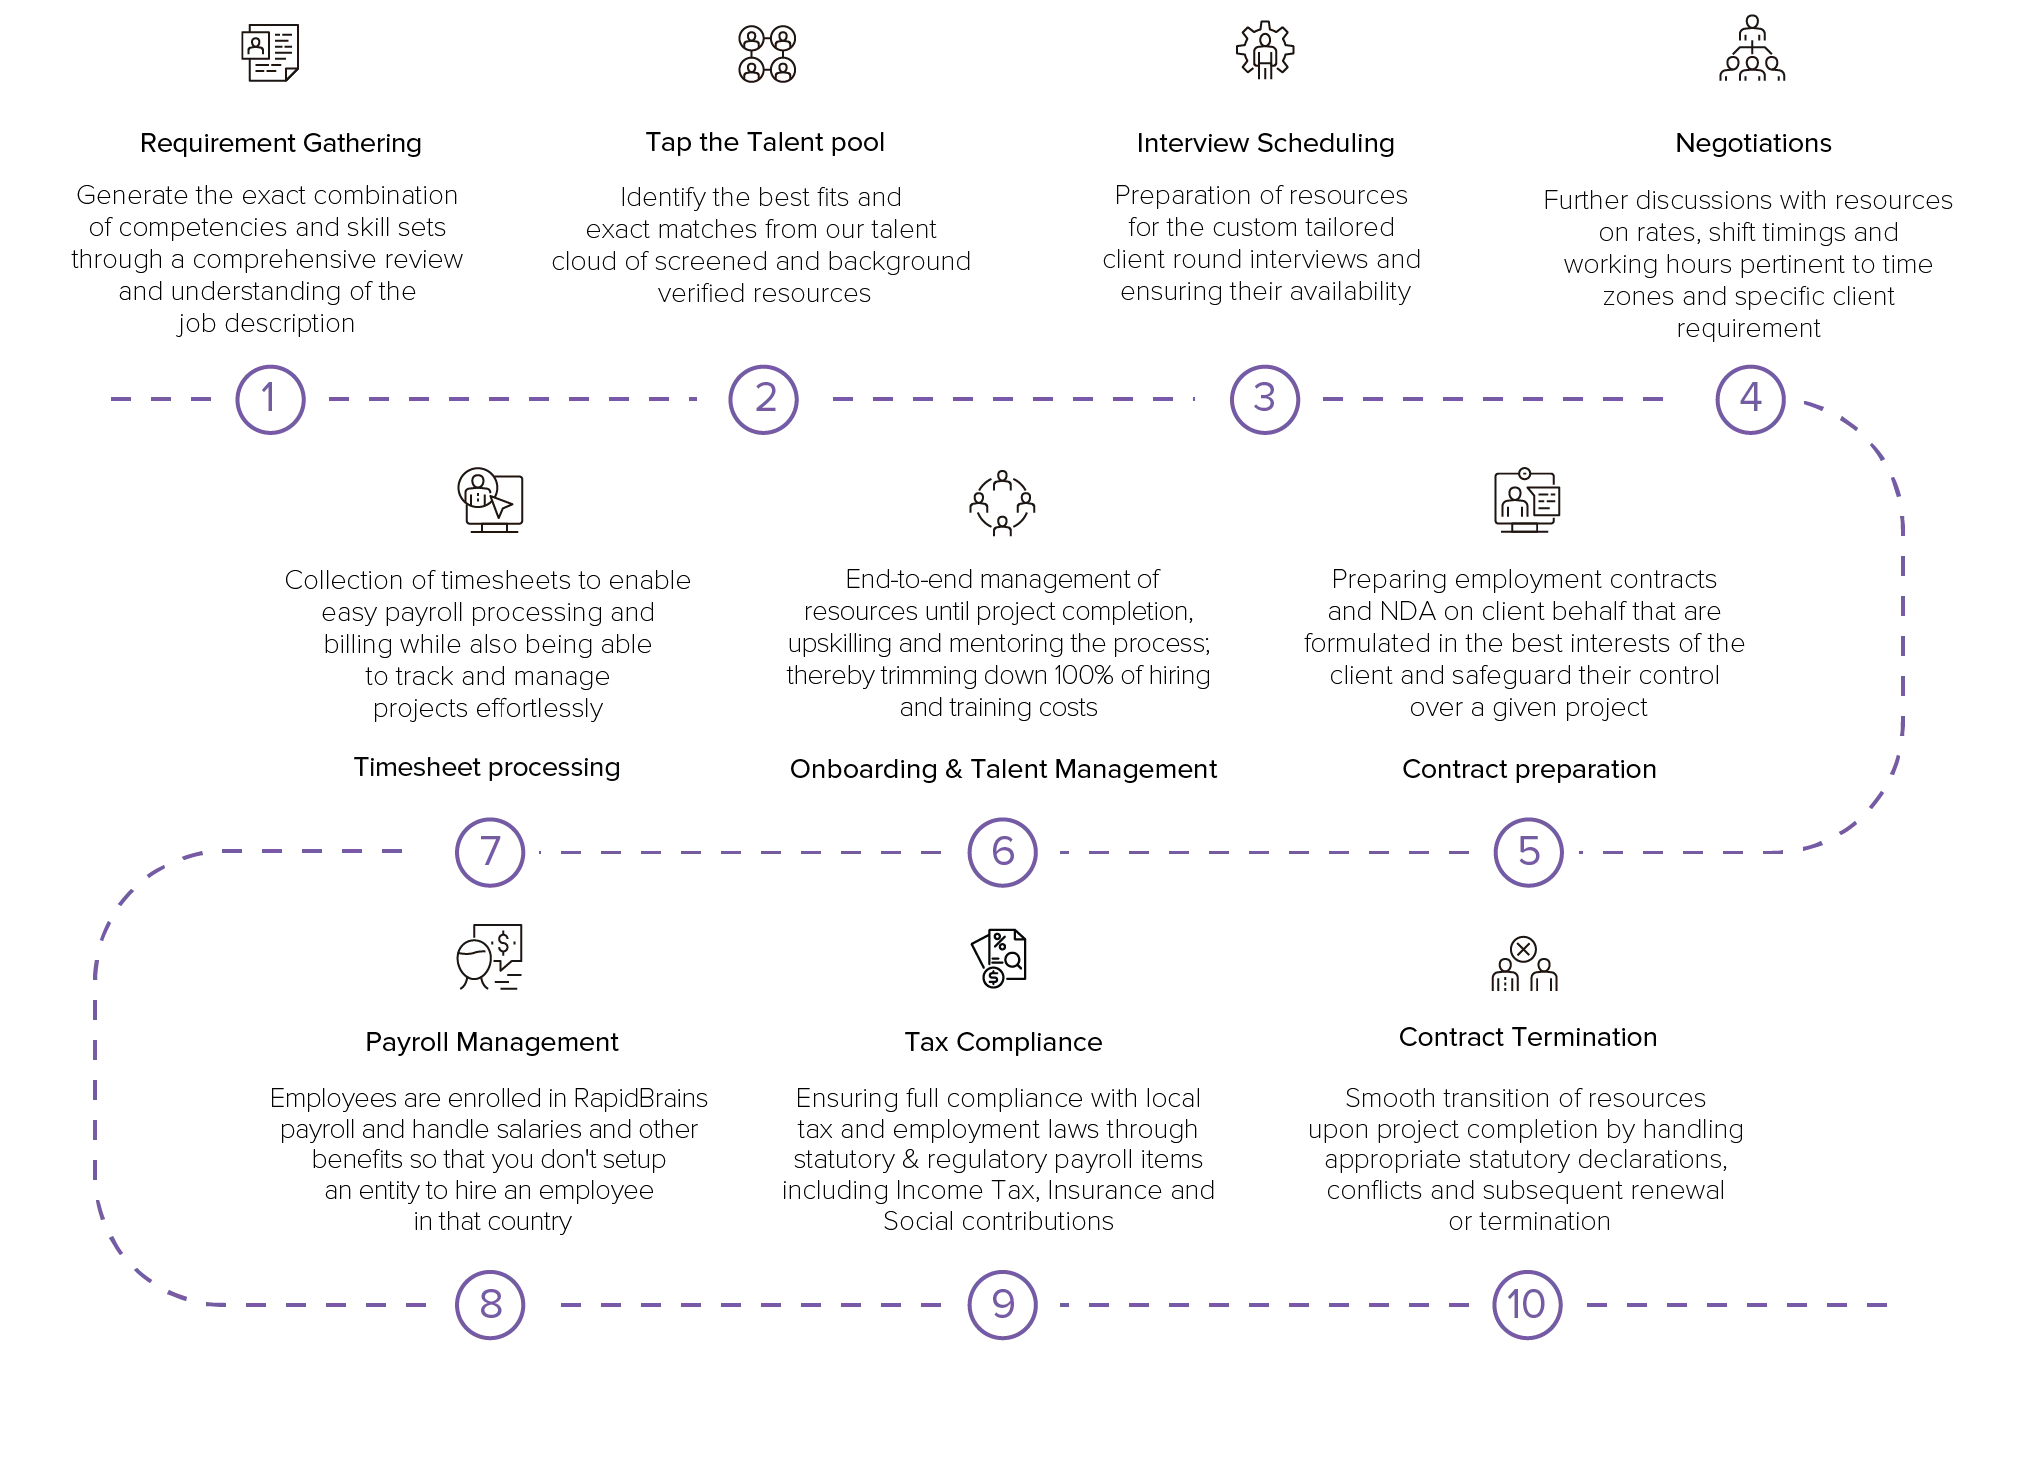
RapidBrains screening process
Structured screening & technical evaluation
With a pre-vetted talent pool of 500,000+ skilled remote developers, candidates undergo in-depth assessments with our in-house technical experts to validate their experience, technical proficiency, and problem-solving abilities.
- Comprehensive First-Level Evaluation Conducted by Our In-House Experts
- Evaluation of past project experience & problem-solving skills
- Communication & soft skills assessment for remote work readiness
On-Demand skill assessment based on client specification
We offer customized skill assessments based on client requests. Clients can select from a variety of evaluation methods to ensure the best talent fit.
- Technology-specific coding tests & project-based evaluations
- Live coding challenges & pair-programming sessions
- Integration with client-preferred interview or assessment platforms
Background verification & compliance assurance
We ensure a thorough verification process before onboarding, covering employment history, identity checks, and legal compliance.
- Advanced background & identity verification with employer references
- Final interview for cultural fit & client approval
- Onboarding & legal compliance handling, including payroll & contracts
Core Technical Capabilities
RapidBrains gives you a global pool of pre-vetted remote engineering talent, ready to onboard in under 24 hours. Our Compiler & Agentic AI Engineers bring deep expertise in IR optimization, low-level execution runtimes, hardware acceleration, and autonomous multi-agent frameworks.

Custom AI Compiler Development
Design IR transformations, pass management, and graph-lowering pipelines utilizing LLVM and MLIR to squeeze maximum performance out of underlying hardware.

Agentic Execution Engines
Architect stateful, multi-agent frameworks featuring dynamic routing, tool execution loops, context management, and long-term memory integration.

Low-Level Compute & Memory Optimization
Eliminate latency bottlenecks through custom kernel tuning (CUDA/Triton), quantization, zero-copy memory access, and specialized memory allocation strategies.

Distributed AI Runtime Infrastructure
Deploy scalable runtimes built for parallelized agent orchestrations, handling human-in-the-loop triggers, fallback handling, and fault-tolerant agent state persistence.
Associated technology stacks
| LLVM | MLIR | Apache TVM | GCC | XLA | ONNX Runtime | vLLM |
| TensorRT | Llama.cpp | TGI | OpenVINO | LangGraph | CrewAI | AutoGen |
| LlamaIndex | Semantic Kernel | C++ | Rust | Python | CUDA | Triton |
Everything you need to know
If you couldn't find the answer to your question, please check our FAQ page or reach us via our contact form.
<p dir="ltr">Selected engineers can start within 24 hours of final interview approval. They arrive equipped to fit into your existing Git workflows, CI/CD pipelines, and project management tools immediately.</p>
<p dir="ltr">We match you with talent providing a minimum of 4 to 5 hours of direct overlap with your core operating hours, regardless of whether your team is based in the US, Europe, or APAC.</p>
<p dir="ltr">Our rigorous evaluation process includes live low-level coding challenges (C++/Rust/CUDA), system architecture design assessments focused on agentic loops and compiler passes, and an evaluation of communication skills.</p>
<p dir="ltr">If an engineer does not meet your expectations during this window, we replace them immediately or refund your initial deposit with no questions asked.</p>